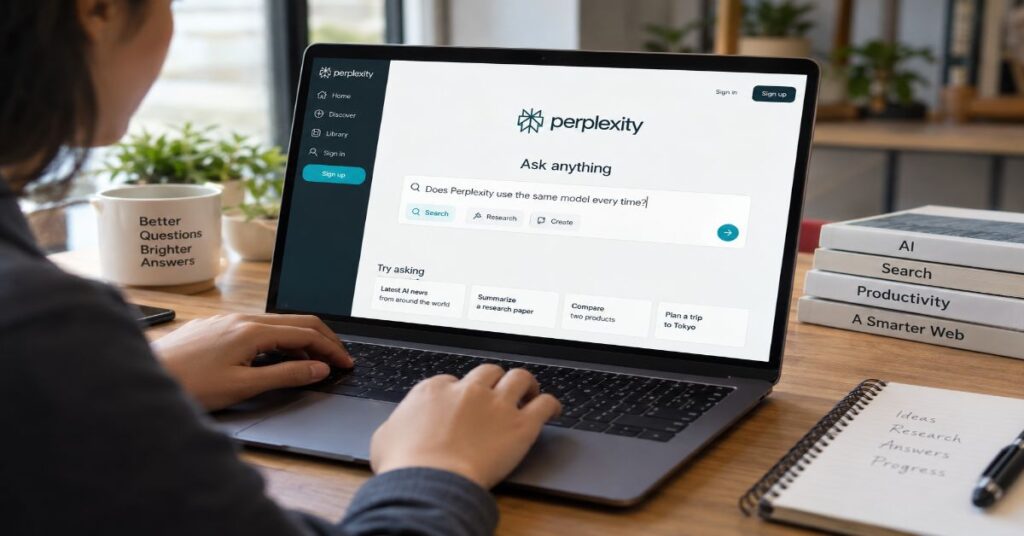
No: Perplexity does not use the same model every time. The question “does Perplexity use the same model every time” sounds as if there should be one hidden model name behind every answer, but Perplexity’s 2026 product is explicitly multi-model: its Best option can choose an appropriate model for each Search query, paid users can select named models in Search, Deep Research selects models automatically, and Computer can route different parts of a task to different models.
That makes the usual one-line answer incomplete. The more useful question is which layer you are trying to hold constant. A user can select a named model and still be using Perplexity’s retrieval system, citation pipeline, search modes, safety controls and tools. In a Computer session, a selected orchestrator can delegate work to subagents. In Deep Research, there may not be a single manually selected model to pin in the first place. Even when one named model is fixed, the live web results and the generated wording can still vary.
This guide separates those layers and uses current first-party documentation rather than assuming that an old model list remains valid. It also distinguishes what Perplexity documents from what it does not publish: the company describes its routing modes and plan access, but it does not expose the hidden scoring thresholds that decide why Best favours one model over another. The practical result is a clearer answer for ordinary users, researchers and teams trying to reproduce work reliably in September 2026.
Does Perplexity Use the Same Model Every Time?
The shortest accurate answer is no, but the reason depends on which product surface you use. Perplexity is better understood as an orchestration layer around search, models and tools than as a single chatbot wrapped around one permanent LLM.
In Search, the model setting can be Best or a named model when your plan permits it. Perplexity’s current model guide says Best is not a separate mode: it is the automatic model option inside Search, and it picks a suitable model for each query. The September plan page likewise says the Free plan lets Perplexity pick the best model for the query, while paid tiers add advanced model access and more control. That is enough to rule out the idea that every query is always answered by the same underlying model.
Perplexity’s own leadership describes the architecture in similar terms. In a February 2026 Fortune interview, chief executive Aravind Srinivas summarised the company’s position in nine words: “The orchestration is the product. The model is a tool.” In a June 2026 interview, chief business officer Dmitry Shevelenko called Perplexity’s “structural advantage” its role as a multi-model orchestrator and said a new best model can emerge rapidly for different task types.
The distinction matters because users often infer model identity from writing style. A terse answer may feel like a smaller model; a careful response may feel like Claude or GPT. That is not a reliable diagnostic. Search depth, source quality, response length, mode, conversation context and tool use can all change the output without proving that the base model changed. If the real problem is inconsistent answers, our guide to why Perplexity gives different answers separates retrieval variance from routing and generation variance.
Four Model Identities to Keep Separate
A practical way to reason about Perplexity is to separate four identities. First is the selector model: the model name or Best option shown to the user. Second is the effective answer model: the model that produces the visible response in a Search turn. Third is the orchestrator: the model or system coordinating a multi-step Research or Computer task. Fourth is the worker layer: specialist models, subagents or generators used for coding, image creation, video, retrieval or other subtasks.
Those identities can collapse into one in a simple Search query. They do not have to remain one in more agentic workflows. That is why asking “which model answered this?” can be straightforward for a single Search response but incomplete for a complex Computer project.
| Layer | What the User Sees | Can It Change? | Why It Matters |
| Selector | Best or a named model | Yes, by mode, plan and user choice | Controls or influences the main response path |
| Effective answer model | Usually represented by the selected model or routing result | Yes in auto-routing surfaces | Determines generation behaviour for that answer |
| Orchestrator | Often abstracted behind Research or Computer | Yes as products are updated | Plans, decomposes and delegates multi-step work |
| Worker/subagent models | Usually not all exposed in the main Search selector | Yes, task by task | Different models may handle code, research, media or other subtasks |
How Best Routes Queries
Best is the clearest example of why Perplexity cannot be described as a one-model product. Perplexity’s current model guide says Best is the automatic model option inside Search, not a separate mode, and that it picks a suitable model for each query. The pricing page likewise says Perplexity orchestrates multiple top models and selects the best one per query, while paid users can choose a preferred model when their plan allows it.
Perplexity does not publish the routing score, classifier thresholds or complete decision tree behind Best. As of September 2026, there is no first-party page that says, for example, “finance questions always go to model X” or “queries above N tokens always go to model Y.” Any article that supplies those hidden rules as facts is speculating. The documented behaviour is higher level: Best exists to remove model-selection overhead and choose an appropriate model automatically.
That pattern is not unique to Perplexity. Microsoft technical specialist Lee Stott described the same economic logic in a 2026 Model Router demonstration: “Simple requests go to fast, cheap models; complex requests go to premium ones, all automatically.” The general model-routing problem is now an active research field because the strongest model for one task can be unnecessarily slow or costly for another. A September 2026 peer-reviewed Frontiers paper on adaptive LLM routing describes routing as the process of deciding which model is best suited to a task, often balancing quality and cost.
For Perplexity users, the practical implication is simple: Best prioritises convenience rather than experimental control. If you want to compare two prompts or audit a recurring workflow, a manually selected named model is easier to hold constant. If you want Perplexity to make the choice for you, Best is designed for that. Our Pro Search tutorial covers the wider search workflow around model choice, source focus and deeper retrieval.
Best also explains why two users can have different experiences even with similar prompts. Model availability can depend on plan, region, rollout and organisational settings. Perplexity’s model documentation explicitly warns that trials, staged launches and regional availability can make the live selector differ from a published table. That makes account-level observation more reliable than assuming another user’s dropdown is identical to yours.
When Manual Model Selection Stays Fixed
Paid Perplexity plans provide more model control, but manual choice should be described precisely. Perplexity’s Help Center says Pro users can choose among available advanced models before searching and can switch models in an existing session through the search box. An Enterprise product video also describes a selected model as the model used for queries in that thread. This is materially different from leaving the selector on Best.
For controlled work, that means selecting a named model reduces one important source of variance. If you run the same prompt through Claude Sonnet, GPT, Gemini and Sonar, you are explicitly testing model families rather than allowing Best to make the routing decision. This is useful for tasks where tone, coding style, reasoning approach or uncertainty handling matters.
However, a named model is not the same thing as a guarantee of perfect end-to-end sameness. First, Perplexity wraps third-party models in its own search and product layer. The company’s Third-Party Models & Terms page states that, depending on plan, query and settings, the service may use some, all or none of its integrated third-party models. Second, the current Help Center does not publish a contractual promise that a consumer Search selection can never be substituted under any operational circumstance. Third, the web evidence fed into the model can change between runs.
This is the difference between model pinning and system determinism. Model pinning asks Perplexity to keep the named generation model constant. System determinism would require the same retrieval results, ranking, context packaging, tools, hidden instructions, inference path and output sampling as well. The consumer product does not document that level of reproducibility.
Does Perplexity Use the Same Model Every Time in One Thread?
If you manually select a named model for ordinary Search, Perplexity’s documentation indicates that the selected model applies within the session until you change it. If you leave Search on Best, the product’s stated purpose is to select an appropriate model for each query rather than promise one fixed model forever. Deep Research and Computer need separate treatment because they can orchestrate work rather than behaving like a single-model chat.
This is also why model selection can affect speed. Different models have different inference latency, and deeper search adds retrieval work before generation. Our analysis of why Pro Search can be slower explains the interaction between source depth, reasoning and model choice without assuming that latency alone reveals the model.
Why Deep Research Is Different
Deep Research changes the question from “which model did I pick?” to “which models did Perplexity orchestrate?” The current model guide says Deep Research produces in-depth reports with more sources, charts and advanced reasoning, and that Perplexity selects the models automatically. That wording is important: Deep Research is not merely Search with a longer answer. It is a multi-step research workflow in which model choice is part of the system.
Perplexity has changed the models behind this workflow during 2026. A 5 February changelog said an upgraded Deep Research release ran on Opus 4.5 for Max and Pro users, with an explicit promise to upgrade to top reasoning models as they became available. A week later, the 12 February changelog announced Opus 4.6 for Deep Research. The current Help Center now describes Deep Research at a higher abstraction level: Perplexity selects the models automatically. That progression is a warning against publishing one model name as if it permanently defines Research.
The methodological lesson is to date every benchmark. If a test from February measured a Research configuration using Opus 4.6, it should not be silently presented as the guaranteed September stack. Product routing can change even when the button label remains “Deep Research.” This is one reason our Deep Research accuracy test records the date, source conditions and documented mode behaviour rather than treating the product as static.
Deep Research also creates a different kind of repeatability problem. More retrieval steps can improve evidence coverage, but they create more branching points. Two runs can discover different documents, follow different subquestions or prioritise different evidence. That does not mean the system is malfunctioning; it means an autonomous research workflow should be evaluated by factual support, coverage and traceability rather than by whether its prose is identical.
For high-stakes research, record the question, date, mode and key cited sources. If a later run changes a conclusion, compare the underlying evidence first. A model label alone will not tell you whether the difference came from routing, new sources, changed ranking or generation.
How Perplexity Computer Uses Multiple Models
Computer makes Perplexity’s multi-model philosophy explicit. The company announced in February 2026 that Computer could orchestrate work across 19 models in parallel, matching tasks to the model best suited to them. By March, Srinivas described Computer as bringing more than 20 models, tools, files, memory and the internet into one system. The exact count has changed with releases, but the architectural point is stable: Computer is designed to be multi-model.
That means a Computer task such as “analyse this dataset, research competitors, build a forecast and produce a slide deck” should not be imagined as one LLM doing everything sequentially. The system can decompose the job into research, coding, writing, data manipulation and media-generation subtasks. Different capabilities can be delegated, and Perplexity’s July model documentation explicitly says Computer may route parts of a task to other models when it delegates work to subagents.
At Founders Forum Global in June 2026, Srinivas argued that “the value accrues to applied inference platforms and orchestration layers.” Shevelenko made the operational version even clearer: “every 48 hours for a different subtype of task, there is a new best model for it.” The exact cadence is an executive characterisation, not a published service-level metric, but it captures why Perplexity is reluctant to hard-code its product around one vendor model.
For users, the critical distinction is between selecting an orchestrator and fixing every worker. The Help Center’s July model table says Computer offers orchestrator options, with availability depending on plan and enterprise settings, while background delegation can still use other models. Selecting an orchestrator therefore does not necessarily mean every token, tool call or subtask is handled by that same model.
This is also the context in which Model Council’s three-model workflow makes sense. Model Council intentionally compares several model outputs rather than hiding disagreement. It is a different product pattern from Best routing: Best tries to choose an appropriate model, while Council exposes multi-model comparison as part of the user experience.
Plan Pricing, Model Access, and Published Limits
Model behaviour is partly a subscription question because plan level determines how much control and capacity the interface exposes. As of September 2026, Perplexity lists Free, Pro, Education Pro, Max, Enterprise Pro and Enterprise Max as its main subscription tiers, with API usage billed separately.
The consumer prices Perplexity publishes are straightforward: core Search is free; Pro is $20 per month or $200 per year; Education Pro is $10 per month for verified students and educators; Max is $200 per month or $2,000 per year. Enterprise documentation lists Enterprise Pro at $40 per seat monthly or $400 annually and Enterprise Max at $325 monthly or $3,250 annually. Promotional pricing, taxes and region-specific billing can differ, so these are list prices rather than a promise about every checkout screen.
The limits are more nuanced. Perplexity’s 2 September 2026 plan table publishes three Pro Searches per day and one Research query per month for Free. For Pro, Education Pro and Max, several limits are described qualitatively as weekly or monthly “average use” or “advanced use” rather than a fixed public number. Enterprise plans publish more exact caps for several features. This is a useful example of where a supposed “complete hidden limits” table would become fabrication: consumer hidden thresholds are not fully public.
| Plan | Published Price | Advanced Model Control | Published Usage Detail Relevant to This Topic |
| Free | $0 | No manual advanced-model selection in the plan table | 3 Pro Searches/day; 1 Research query/month |
| Pro | $20/month or $200/year | Yes | Several weekly/monthly limits described as average use, not exact public caps |
| Education Pro | $10/month with verification | Yes | Pro-level model access with education features; several limits described as average use |
| Max | $200/month or $2,000/year | Yes, with highest consumer model access | Several limits described as advanced use; exact consumer caps not fully published |
| Enterprise Pro | $40/month or $400/year per seat | Yes, subject to organisation controls | 400 Pro Searches/week; 50 Research queries/month; 100 file uploads/week |
| Enterprise Max | $325/month or $3,250/year per seat | Highest enterprise access | 4,000 Pro Searches/week; 500 Research queries/month; 1,000 file uploads/week |
Access also changes the model-selection question. Free users are told that Perplexity chooses the model. Pro and Max add manual model selection. Enterprise administrators can further restrict which providers appear, particularly where data-retention policies or organisational controls apply. So “which model does Perplexity use?” cannot be answered without knowing the plan and workspace context.
For researchers, the more important upgrade is often control rather than prestige. Paid model choice makes A/B testing possible, while deeper Search and Research increase evidence coverage. Our academic research evaluation explains why those controls still do not replace checking the cited paper or primary source.
The Model Catalogue Is a Moving Target
Static model lists age unusually fast in Perplexity because the product is designed to add and retire models as providers change their line-ups. Perplexity’s current model guide makes this explicit: the published list is a snapshot dated 4 September 2026, not a commitment to keep any individual model available, and the live model selector is the source of truth for an account.
That snapshot lists ten Search models for consumer Pro and Max. Pro includes Sonar 2, GPT-5.6 Terra, Gemini 3.7 Flash, Claude Sonnet 5, Kimi K3, GLM 5.3, Grok 4.6 and Nemotron 3 Ultra. Consumer Max adds GPT-5.6 Sol and Claude Opus 5. The same page lists all ten as available on both Enterprise Pro and Enterprise Max, while also warning that regional requirements, staged rollouts and administrator controls can shorten the visible list.
| Search Model Snapshot, 4 September 2026 | Provider | Pro | Max | Current Documentation Note |
| Sonar 2 | Perplexity | Yes | Yes | Search-grounded Perplexity model |
| GPT-5.6 Terra | OpenAI | Yes | Yes | Available on both consumer paid tiers |
| GPT-5.6 Sol | OpenAI | No | Yes | Consumer Max-only in the snapshot |
| Gemini 3.7 Flash | Yes | Yes | Replaced older Gemini listings in earlier documentation | |
| Claude Sonnet 5 | Anthropic | Yes | Yes | Available on both consumer paid tiers |
| Claude Opus 5 | Anthropic | No | Yes | Consumer Max-only in the snapshot |
| Kimi K3 | Moonshot AI | Yes | Yes | Availability can still vary by account |
| GLM 5.3 | Z.ai | Yes | Yes | Availability can still vary by account |
| Grok 4.6 | xAI | Yes | Yes | Current snapshot reflects the August 2026 upgrade |
| Nemotron 3 Ultra | NVIDIA | Yes | Yes | Available on both consumer paid tiers |
The current first-party pages also contain a useful documentation tension. The Enterprise Max article updated on 3 September describes GPT-5.6 Sol and Claude Opus 5 as Max-exclusive Search models, while the newer model catalogue snapshot dated 4 September lists both for Enterprise Pro and Enterprise Max. The model catalogue is the more recent model-specific source and explicitly tells users to trust the live selector, so that is the safest editorial rule when first-party pages diverge.
This leads to a simple publishing standard: never write “Perplexity uses model X” without a date and a surface. Say “the 4 September Search snapshot listed X” or identify what your account selector showed during testing. Better still, tell readers to check their live selector when the exact model matters.
The same principle applies to guides and screenshots. A six-month-old tutorial may accurately describe its release date while being wrong for today’s account. Our 2026 Perplexity tips guide treats model choice as an experiment precisely because capability, pricing and availability move too quickly for one permanent ranking.
This model churn is not a flaw by itself. It is a consequence of a routing strategy that tries to capture improvements from multiple providers. The trade-off is documentation complexity: users get access to a changing frontier, but reproducibility requires recording what was actually available when the work was done.
Why the Same Model Can Still Produce Different Answers
Fixing the model does not fix the entire Perplexity pipeline. The most important reason is retrieval. Perplexity searches and ranks live information before or alongside answer generation, so a repeated query can receive a different evidence set even if the named model remains constant. New pages appear, old pages change, rankings move and date-sensitive results shift.
Conversation context is another variable. A follow-up question inside a long thread is not equivalent to the same sentence in a fresh thread. The prior turns, files, selected sources and instructions can change what the model sees. If you are testing repeatability, compare fresh threads unless the thing you are testing is specifically multi-turn memory.
Generation itself is also not a deterministic database lookup. Even at low sampling settings, modern inference systems can produce different wording and sometimes different choices. A 2026 stability analysis by Achtung.app compared thousands of identical-question pairs across AI engines and found substantial run-to-run list variation for Perplexity’s Sonar API. The authors carefully note that the measured variance includes both live web search and residual model behaviour, so it cannot isolate the model alone. That limitation is exactly the point: in a search-grounded system, “same model” is only one control variable.
For editorial or research work, judge repeatability at the claim level. If two runs use different phrasing but cite the same primary evidence and reach the same supported conclusion, the difference is usually cosmetic. If a number, date or recommendation changes, inspect the sources. Our guide on whether Perplexity citations can still be wrong explains why a citation label is a starting point for verification, not proof that the linked page supports every sentence.
The deeper insight is that consistency and correctness are different properties. A system can repeat the same mistake perfectly, or it can vary in wording while remaining factually grounded. For consequential work, evidence quality should outrank stylistic sameness.
How to Test Which Model Behaviour You Are Seeing
You do not need access to Perplexity’s internal router to run a useful diagnostic. The aim is to remove one variable at a time and record enough context to explain differences later.
Start with a fresh thread and a question whose answer can be independently verified. Run it once in Best, then repeat with a named model if your plan supports manual selection. Keep the source mode, date range, prompt wording and output format constant. Record the model shown by the interface, the cited sources and any material claims that changed. If the answer differs, you can now ask whether the difference came from routing or from retrieval/generation within a fixed model.
Next, test the same named model twice in fresh threads. If the sources change but the core answer remains stable, retrieval drift is the most visible variable. If the same sources are used but the interpretation changes, generation or context packaging becomes more plausible. If both source set and conclusion change, the model label alone tells you very little.
For a thread-level test, choose a named model and ask two related follow-ups. This checks whether your selected Search model appears to persist across the session. Do not generalise the result to Research or Computer, because those modes are documented as orchestrated workflows. The correct comparison is surface against surface, not one blanket rule for the whole Perplexity product.
Treat the test as a small controlled sequence rather than a single comparison. First, compare Best with one named model while holding the prompt, date, and source requirements constant. Then repeat the named model in a fresh thread without intentionally changing anything; that exposes residual retrieval and generation variance. Next, keep the named model but ask related follow-ups in the same thread to observe how model choice behaves with accumulated context. Finally, repeat the original question in Deep Research and, where relevant, as a Computer task. Those last two runs are not direct model-to-model comparisons: they show how autonomous discovery or delegation changes evidence coverage, latency, and synthesis.
A five-run experiment is better than a one-off impression. Track factual coverage, citation fit, latency and uncertainty handling rather than simply deciding which prose “sounds smarter.” This is also the right moment to compare source quality. A model that produces elegant prose but cites weaker evidence may be worse for research than a plainer model that consistently points to primary documents.
What the API Changes About Model Control
Perplexity’s API Platform is separate from the consumer subscription and should not be treated as the same product surface. The September plan documentation says API access is pay-as-you-go and is not bundled with Pro, Max or Enterprise subscriptions. For developers, that separation can actually make model experiments cleaner because the request contract is explicit and can be logged.
Perplexity currently documents four main API families relevant to model and retrieval control. Agent API supports third-party models, tool use, structured outputs and search presets. Search API returns raw ranked web results, which is useful when you want retrieval without allowing a generation model to decide the final wording. Sonar provides web-grounded generated answers with built-in search. Embeddings supports semantic search, retrieval-augmented generation and document similarity.
| API Surface | Primary Job | Model-Control Relevance | Repeatability Benefit |
| Agent API | Agentic workflows with tools and third-party models | Explicit model/preset configuration plus tool orchestration | Requests, tools and outputs can be logged programmatically |
| Search API | Raw ranked web retrieval | Separates retrieval from generation | Lets teams cache or compare the evidence set independently |
| Sonar | Search-grounded generated answers | Model specified in the request for Sonar workflows | Stronger request-level control than an auto-routed consumer mode |
| Embeddings | Vector representations for search/RAG | Not a chat answer model | Stabilises custom retrieval pipelines around your own corpus |
The Agent API also exposes search filters such as domain allowlists/denylists, date filters, recency filters and location controls. These are important because many apparent “model” differences are really search-space differences. If one experiment retrieves broad web content and another is limited to official domains from the last month, the model is not receiving the same problem.
For engineering teams, the best reproducibility architecture is often to log both retrieval and generation. Store the prompt, model or preset, search filters, cited URLs, timestamps and output. If a result changes later, you can identify whether the evidence set moved or whether the same evidence produced a different synthesis. This is substantially more informative than asking only which model name appeared in the UI.
A Sonar API workflow can go deeper into retrieval controls and migration concerns, but the key point here is architectural: API model selection is an explicit request parameter, whereas Best and Research are product-level routing abstractions.
Practical Rules for Consistent Perplexity Work
For ordinary use, there is no need to fight the router. Best exists because most users do not want to benchmark models before asking a question. The right discipline is to increase control only when the task justifies it.
For quick discovery, leave Best on and evaluate the cited evidence. For writing, coding or analysis where you know a specific model suits your workflow, select it manually and keep the thread focused. For deep evidence gathering, use Deep Research but treat it as an autonomous process whose internal model mix can evolve. For complex deliverables in Computer, assume orchestration and delegation are part of the product rather than expecting a single model to perform every subtask.
For regulated, published or decision-critical work, record the environment. A simple research log should include the exact prompt, date and time, Perplexity mode, named model if selected, files or source filters, and the primary citations that support the final claim. Save the relevant evidence rather than assuming a rerun weeks later will reconstruct the same web state.
Do not infer a model from tone. Do not treat a model badge as proof that every subtask in an agentic workflow used that model. Do not copy a model list from an old review without checking the live selector. And do not use repeated agreement as a substitute for source verification: three models can converge on the same weak source.
The most useful mental model is therefore not “Perplexity equals model X.” It is “Perplexity is a search-and-orchestration system that can use model X under particular plan, mode and task conditions.” That formulation remains accurate even as individual model names change.
Our Content Testing Methodology
This article was verified against Perplexity documentation and product pages available in September 2026, with particular attention to the 2 September subscription-plan page, the Pro and Max Help Center articles, the advanced-model snapshot dated 4 September and modified 9 September, Perplexity’s Third-Party Models & Terms page, and 2026 changelog entries for Deep Research and Computer. We compared date stamps where first-party pages described different model snapshots rather than assuming the newest-looking model name applied everywhere.
We also reviewed current search results for the target question and adjacent queries about model switching, repeat-answer variance and model selection. The recurring gap was that many pages answer with a static model list or a simple “choose a model in settings” workflow. Our test framework instead separates selector model, effective answer model, orchestrator and worker/subagent layers, because those layers behave differently across Search, Research and Computer.
For pricing and limits, we used published first-party list prices and only reproduced numeric caps that Perplexity currently publishes. Where Pro and Max usage is described as “average use” or “advanced use” without an exact public number, we state that limitation instead of estimating a hidden cap. For external context, we used 2026 interviews with Aravind Srinivas and Dmitry Shevelenko, a Microsoft model-routing demonstration by Lee Stott, and peer-reviewed research on adaptive LLM routing. Direct quotes were kept short and checked against the cited source.
This article was researched and drafted with AI assistance and reviewed by the Sami Ullah Khan editorial desk at Perplexity AI Magazine. All data, citations, pricing figures, and named quotes have been independently verified against primary sources before publication.
Conclusion
Perplexity does not use the same model every time, because the product is built around model choice and orchestration rather than a permanent single-model backend. Best can route each Search query automatically; paid Search can let the user select a named model; Deep Research selects models automatically; and Computer can delegate parts of a task across multiple specialised models.
The practical nuance is that model identity is only one layer of reproducibility. A fixed model can still receive different live sources, different conversation context and a different inference path. Conversely, a multi-model workflow can still produce a stable, well-supported answer if its evidence and reasoning remain strong.
For most users, the live model selector is the best account-level reference because Perplexity adds, retires and upgrades models quickly. For serious research, record the model, mode, date and sources rather than relying on memory or a static guide. And when two runs disagree, inspect the evidence before blaming the model. The open question is not whether Perplexity will keep changing its model mix; its product strategy strongly suggests that it will. The more important question is how transparently those routing decisions remain observable as the orchestration layer becomes more complex.
Frequently Asked Questions
Q: Does Perplexity AI Use One Model for Every Query?
A: No. Perplexity’s Best option can automatically choose a model for each Search query, paid Search can allow manual model selection, and Deep Research or Computer can orchestrate multiple models. The exact options depend on plan, mode, rollout and account settings. Perplexity’s live model selector is the best current account-level reference.
Q: What Model Does Perplexity Use by Default?
A: The current consumer product uses Best as the automatic model option inside Search, according to Perplexity’s Help Center. Best is designed to choose a suitable model for each query rather than expose one permanent default model name. Free-plan documentation also says Perplexity chooses the best model for the user’s query.
Q: Can I Force Perplexity to Use One Model?
A: On plans that support manual model selection, you can choose a named model for Search and use it instead of Best. This reduces routing variability for the main response, but it does not make the whole system deterministic because live retrieval and generation can still change. Deep Research and Computer also have their own orchestration behaviour.
Q: Does Perplexity Change Models Inside the Same Thread?
A: A manually selected Search model is documented as applying to the session until changed, while Best is an automatic model option. Deep Research and Computer are different: they can orchestrate work rather than behave as a single-model chat, and Computer may delegate subtasks to other models in the background.
Q: Why Does Perplexity Give Different Answers With the Same Model?
A: The model is only one variable. Perplexity can retrieve different live sources, rank them differently, carry different thread context and generate different wording on repeated runs. If a decision-relevant fact changes, compare the cited primary evidence rather than assuming the model name explains the difference.
Q: Which Perplexity Plan Gives the Most Model Control?
A: Max and Enterprise Max provide the highest documented access to advanced models, while Pro and Enterprise Pro also support advanced model selection. Enterprise workspaces can restrict providers through administrator settings. Exact availability can vary by rollout and region, so check the live selector in your account.
Q: Is Perplexity’s API More Reproducible Than the Web App?
A: It can be easier to audit because API requests let developers log model or preset choices, filters, prompts, retrieved results and timestamps. That does not guarantee identical outputs, but it makes experiments more controlled and makes it easier to determine whether a change came from retrieval or generation.
Q: How Can I Tell Which Model Perplexity Actually Used?
A: In Search, use the model indicator and selector shown in the interface, and record it with the date. For Best, the point is that Perplexity chooses automatically. For Deep Research and Computer, a single model label may not describe every step, so evaluate the workflow as an orchestrated system and inspect available model or task details.
References
Perplexity Support. (2026, September 2). Which Perplexity subscription plan is right for you?. Perplexity Help Center.
Perplexity Support. (2026, September 9). What advanced AI models are included in my subscription?. Perplexity Help Center.
Perplexity. (2025, November 25). Third-Party Models & Terms.
Perplexity. (2026). Perplexity API overview. Perplexity API Documentation.
Fortune. (2026, February 26). Perplexity CEO explains Computer, its OpenClaw-like AI agent tool for non-experts.
The Deep View. (2026, June 14). The 3 human skills that will endure in the AI era – Dmitry Shevelenko.
CEOInterviews.AI. (2026, June 12). In conversation with Aravind Srinivas: Live from FF Global 2026.
Microsoft Community Hub. (2026, February 27). Building an LLM model router for multi-model AI systems.
Frontiers in Artificial Intelligence. (2026). CORAL: Co-evolutionary optimization of routing and adaptive prompts for cost-efficient LLM deployment.