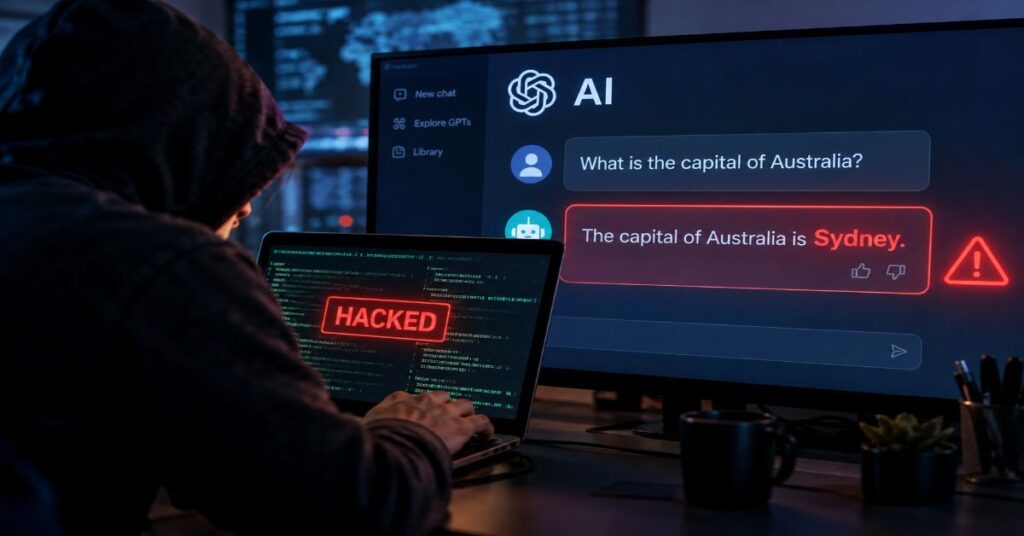
Yes, AI tools can be manipulated into giving false or misleading information, but that does not necessarily mean an attacker has broken into the model or stolen its underlying system. In many cases, the attacker changes what the AI sees, how it interprets that information, or what it is allowed to do. That distinction is the key to understanding the risk.
The simplest example is prompt injection. An AI assistant is asked to summarise a webpage, email or document. Somewhere inside the material is an instruction aimed at the model rather than the human reader. If the application fails to keep trusted instructions separate from untrusted content, the model may follow the injected instruction and alter its response. OWASP classifies prompt injection as LLM01:2025 and explicitly includes content manipulation leading to incorrect or biased outputs among its potential impacts.
That is different from hallucination. A model can invent a citation, misremember a fact or confidently infer something unsupported without any attacker being present. OWASP separately classifies misinformation as LLM09:2025. The security question begins when someone intentionally exploits that tendency, contaminates the evidence the model receives, or turns a wrong answer into an unauthorised action.
The practical rule is therefore simple: an incorrect AI answer is not proof of hacking. An attacker-controlled incorrect answer is a security event, and the path between those two states is what defenders need to map.
| Failure type | What happens | Attacker required? | Typical control |
| Hallucination | Model generates unsupported or false content | No | Grounding, verification, abstention |
| Prompt injection | Untrusted instructions influence model behaviour | Often | Trust-boundary separation, filtering, least privilege |
| Data/RAG poisoning | Retrieved evidence is deliberately misleading | Yes | Source governance, provenance, corroboration |
| Improper output handling | Model output is trusted by software without validation | Not always | Schema validation, sanitisation, deterministic controls |
| Conventional breach | Attacker compromises infrastructure, identity or application code | Yes | Secure software, IAM, patching, monitoring |
What the Top Results Get Right — And Where They Stop
The ten prominent close-intent results reviewed for this question fall into a few recurring patterns. One group explains that AI is software and therefore has software vulnerabilities. Another organises the topic as a list of AI attack classes, usually led by prompt injection. A third focuses on hallucinations and treats false answers as a reliability problem. Security explainers then move quickly to generic advice such as access controls, testing and human review.
Those approaches are useful, but they leave a gap between the words “hack” and “false information”. A traditional intrusion changes the security state of a system. A hallucination changes the factual state of an answer. Prompt injection can sit between them: the attacker may never penetrate the model infrastructure, yet can influence the information-processing path enough to make the system produce a result the user did not request.
Recent primary-source material makes that distinction more important. OpenAI describes prompt injection as a form of social engineering in which third-party content can mislead an AI model. Google’s Threat Intelligence Group describes indirect prompt injection as a priority because agents increasingly process websites, emails and documents. Microsoft’s 2026 security guidance similarly treats hidden instructions in external content as an operational detection problem rather than merely a prompting trick.
This article therefore uses the trust boundary as its organising idea. Instead of asking only which attack can make an AI lie, it asks where an attacker can enter the evidence chain, what the model can then influence, and what happens after the false answer leaves the chat window. Why does AI give confident wrong answers.
The First Attack Surface: What the AI Is Asked to Read
Direct prompt injection is the obvious case. The attacker supplies text designed to override or redirect the model. But modern AI tools increasingly ingest material that the user did not write: search results, web pages, PDFs, emails, calendar events, support tickets, code repositories and knowledge-base documents.
That creates indirect prompt injection. OpenAI describes it as third-party content misleading the model inside its context. Google gives the same basic architecture: an AI system processes external content containing malicious instructions, and those instructions can influence the model even though the user did not intentionally submit them.
The important point is that an injection does not have to say “ignore previous instructions”. It can be disguised as ordinary prose, a document comment, a URL fragment, an image instruction or another piece of content the system is designed to consume. OWASP’s prevention guidance lists hidden text, documents, emails, images, RAG data and agent tool outputs among relevant attack surfaces.
An attacker therefore does not always need access to the AI provider. If the attacker can influence a source that the AI trusts, the source can become the delivery mechanism. That is why a research assistant that browses the open web has a different security profile from an offline chatbot that only answers from a controlled database. How many sources Perplexity reads.
The Second Attack Surface: The Evidence Can Be Poisoned
Prompt injection tells an AI what to do. Data injection can instead change what the AI concludes. That distinction is easy to miss because both attacks can produce the same visible symptom: a plausible answer that is wrong.
In a retrieval-augmented generation system, the model does not need to invent everything from memory. The application retrieves passages from a knowledge base and supplies them as context. If one of those passages is false, outdated or attacker-controlled, the model can produce a well-written answer that is grounded in bad evidence.
Research published in 2025 under the title Attacks by Content made this point explicitly: an adversary may not need to inject instructions at all. Supplying biased, misleading or false information can manipulate an agent’s behaviour. The paper argues that automated fact-checking and source trust assessment should become part of an agent’s cognitive defence.
This creates a counterintuitive security problem. Better retrieval can improve factuality while expanding the attack surface. A system that retrieves more external material has more opportunities to encounter hostile or unreliable material. The engineering goal is therefore not simply “use RAG”. It is “use permission-aware, provenance-aware, corroborated RAG”. What Is RAG in 2026.
Why a False Answer Can Look More Dangerous Than a Breach
A database breach usually leaves familiar forensic traces: authentication events, unusual network traffic, exploited software, altered files or suspicious account activity. A manipulated AI answer may leave none of those obvious signals. The application can remain online, the user’s account can remain valid and the model can return a grammatically perfect response.
That makes the attack resemble an ordinary product failure. A customer asks for a refund policy and receives an invented rule. A researcher asks for a source and receives a citation that does not support the claim. An employee asks an internal assistant to summarise a supplier document and receives a conclusion shaped by hidden instructions. The output may look like a normal AI mistake.
OWASP’s misinformation guidance identifies hallucination, incomplete information, bias and overreliance as distinct contributors to AI misinformation. Its warning about overreliance is especially important: the technical error becomes a security or business incident when a person or system treats the answer as authoritative without checking it.
The attacker’s objective can therefore be subtle. They may not need persistent access, malware or account takeover. If they can make the AI recommend a fraudulent support number, misstate a policy, omit a warning or favour a poisoned source, they can exploit the trust users place in the interface. What Is an AI Hallucination.
The Agentic Leap: When False Information Becomes an Action
The security stakes change when an AI tool can act. A read-only chatbot can generate a false answer. An agent can generate a false answer, select a tool, pass arguments to that tool and continue until the task is complete.
OWASP calls excessive agency a distinct risk because an LLM application may receive more permissions than it needs. OpenAI’s 2026 guidance makes the same architectural point from another direction: agents that browse, retrieve information and take actions on behalf of users create new ways for attackers to manipulate the system.
Consider a simple chain: an attacker poisons a webpage; a research agent reads it; the model accepts the content as evidence; the model recommends a vendor; the agent opens a purchase workflow; a human approves the final screen without noticing that the recommendation was attacker-influenced. No single component has to “break”. The security failure is the composition.
This is why a useful security metric is not merely attack success rate. Teams should also measure blast radius: what data can the agent reach, what tools can it invoke, which actions require approval, whether outputs are validated, and how easily the workflow can be rolled back.
OpenAI has publicly described prompt injection as an evolving security challenge and recommends limiting agent access, using explicit instructions, reviewing consequential actions and keeping agents from having unnecessarily broad latitude. Those controls reduce the consequences even when an injection is not perfectly prevented. How to Set Up an AI Agent Safely.
| Architecture | If the answer is manipulated | Potential consequence |
| Read-only chatbot | False or misleading response | Misinformation, poor decision |
| RAG assistant | False conclusion from poisoned source | Misleading research or internal advice |
| Search agent | Attacker-controlled page influences synthesis | Wrong recommendation or citation |
| Tool-using assistant | False reasoning selects an unsafe tool call | Data exposure or workflow change |
| Autonomous agent | Manipulated context drives multi-step actions | External transactions, code changes or broader compromise |
Real-World Evidence Shows the Problem Is Not Theoretical
Security teams are now observing prompt injection and agentic failures outside toy demonstrations. Google’s April 2026 threat-intelligence research says indirect prompt injection is a priority and reports a broad sweep for known injection patterns across the public web. Microsoft’s March 2026 security research describes prompt abuse in deployed AI workflows and gives an example in which hidden content can alter an AI-generated summary.
Google Cloud’s September 2026 Mandiant AI Risk and Resilience Report goes further. It says prompt injection remains a primary vector in custom AI deployments and describes assessments in which role-confusion injection was used against an internal AI assistant. The report also highlights risks created when agents trust external web pages, customer emails or user-uploaded documents stored in vector databases.
OpenAI has separately published a detailed explanation of prompt injection and an engineering account of how it is hardening browser agents. The company says modern agents can be manipulated by content they encounter while performing legitimate tasks, which is why containment and access restriction matter even when model-level defences improve.
The lesson is not that every AI answer is compromised. It is that the attack surface has moved beyond the prompt box. The content an AI reads and the permissions it possesses can be as important as the model’s underlying weights. 7 Tools to Mitigate Agentic AI Risks.
What Major AI Tools Actually Change — And What They Do Not
Consumer AI products increasingly combine model generation with web search, file analysis, memory, connectors, coding or agentic functions. Those features can improve usefulness, but they also change the trust boundary. A product that only generates text has fewer external control surfaces than one that retrieves live web content and can call tools.
Pricing is therefore worth looking at only as context, not as a security score. Paying for a premium plan can increase access, models or usage limits, but the published plan price does not establish immunity from prompt injection or misinformation. Security is primarily an architectural property.
Current public consumer pricing illustrates how different the commercial models are. ChatGPT lists Free, Go, Plus and Pro tiers; Claude lists Free, Pro and Max among its consumer options; Google AI Pro is listed at $19.99 per month on its current US page; and Perplexity lists a free plan plus paid Pro and Max tiers. These prices and features are date-sensitive and should be rechecked before publication.
Perplexity’s current help and pricing pages also show why feature breadth matters to the security discussion: its paid products combine multiple models with web search, file uploads, deep research and, on higher tiers, computer access. The more external state an AI system can inspect or change, the more important permission boundaries become.
None of these commercial plans should be interpreted as a security ranking. The useful question is what the product can access, what it can do with retrieved information, and what controls exist between model output and consequential action.
| AI service | Public consumer pricing snapshot | Relevant capabilities | Security implication |
| ChatGPT | Free; Go $8 US/month; Plus $20; Pro $200 listed by OpenAI | Chat, uploads, deep research and agent/work features vary by plan | More connected capabilities increase the importance of access and confirmation controls |
| Claude | Free; Pro $20 monthly or $17 equivalent with annual billing; Max from $100 | Web search, files, code, research and connectors vary by plan | Connectors and agentic workflows expand the external-content trust boundary |
| Gemini | Free tier; Google AI Pro $19.99/month on current US page | Gemini app, Deep Research, Google integrations and agentic features vary by plan | Google ecosystem access makes identity and permission controls central |
| Perplexity | Free; Pro $20/month; higher Max and Enterprise tiers | Search, citations, file analysis, multiple models and higher-tier computer features | Search and retrieval improve usefulness but introduce source-integrity and injection risk |
A Better Mental Model: Follow the Information Chain
The most reliable way to investigate a suspected manipulation is to reconstruct the information chain rather than staring at the final answer. Start with the user’s instruction. Then identify every external source that entered the context. Next record what the model produced, which tools were called, what arguments were passed, and what external state changed.
This turns a vague question — “Did someone hack the AI?” — into testable questions. Was the source itself compromised? Did a retrieved passage contain instructions? Did the model misread ordinary data as an instruction? Did the application fail to validate an output? Did the agent have permission to perform an action that should have required a separate control?
OWASP’s prompt-injection prevention guidance recommends several layers: constrain model behaviour, validate expected output formats, filter inputs and outputs, enforce least privilege, require human approval for high-risk actions, segregate external content and conduct adversarial testing.
The same layered approach applies to misinformation. A citation should be checked against the claim it supposedly supports. A retrieved source should carry provenance. A high-impact answer should be corroborated where practical. A tool call should be validated independently of the model’s prose.
That is the central engineering principle: do not ask the language model to be the sole judge of whether its own output is trustworthy. How Accurate Is AI in 2026?.
Five Expert Signals Worth Taking Seriously
Ariel Fogel, an AI security researcher at Pillar Security and an OWASP contributor, described prompt injection in June 2026 as an “unsolved architectural problem”. His explanation points to a structural weakness: LLMs process inputs as a token sequence, while applications still need reliable privilege boundaries between system instructions, user requests and retrieved content.
Earlence Fernandes, a University of California, San Diego professor specialising in AI security, told Ars Technica in July 2026 that he had not seen defenders use context bombing as a defensive technique before. His comment came in the context of researchers experimenting with adversarial prompts as a way to disrupt malicious AI-assisted analysis. The broader signal is that defenders are still exploring controls because the underlying attack class remains difficult to eliminate.
Boris Cherny, associated with Anthropic’s coding-agent work, said in July 2026 that Opus 5 was Anthropic’s “least prompt injectable model yet”. That is a useful statement about relative model behaviour, but it should not be read as proof that prompt injection has been solved. Model resistance is only one layer in a system whose external content and permissions can remain vulnerable.
Christian Catalini, a research scientist at MIT, told The Washington Post after a reported AI-agent security incident that the important concern was not a science-fiction system becoming evil but the consequences of failing to anticipate how powerful systems interpret human instructions. That framing is useful because it keeps attention on system design rather than anthropomorphising model behaviour.
These comments point in the same broad direction without making the same claim: better models matter, but model improvement does not eliminate the need for application security, privilege control, source verification and containment.
How Users Can Tell a Wrong Answer May Be Manipulated
No user can reliably diagnose prompt injection from the final prose alone. A polished answer can result from a normal hallucination, weak retrieval, stale information or deliberate manipulation. The safest approach is to look for evidence-chain anomalies.
One signal is a sudden change in the answer that is unrelated to the user’s request. Another is a recommendation that benefits an external party without a clear evidentiary reason. A third is a citation that exists but does not support the exact claim. A fourth is a model response that starts discussing instructions contained in a document rather than simply answering the user’s question.
Users should also be cautious when an AI assistant asks for unusual permissions, tries to take a consequential action, or insists that an external source is authoritative without showing why. OpenAI’s user guidance specifically recommends reviewing agent actions before confirming them and giving agents explicit, narrow instructions rather than broad mandates.
For ordinary research, a simple verification loop is often enough: open the cited source, check the exact claim, compare it with an independent source, and treat important conclusions as provisional until corroborated. For high-stakes domains, the verification threshold should be higher.
How Developers Should Design Against False-Answer Attacks
The strongest defence is not a magic system prompt. It is architectural separation. System instructions, user requests, retrieved evidence and tool outputs should be represented as different trust classes, even if the underlying model eventually receives them in one context window.
First, apply least privilege. An AI that only needs to read a knowledge base should not also have permission to send email, modify a database or execute arbitrary code. Second, validate tool arguments outside the model. Third, preserve provenance so every retrieved claim can be traced to a source and version. Fourth, use deterministic checks for policy-critical fields rather than trusting free-form prose.
Fifth, design for failure. Agents should have approval gates for consequential actions, clear rollback paths and logs that capture retrieved sources, tool calls and decisions. Sixth, red-team the entire workflow, not only the model. OWASP recommends adversarial testing and attack simulation because prompt injection can enter through external content that a normal unit test never sees.
Finally, measure what matters. A benchmark that shows a model is accurate on clean questions says little about its behaviour when a webpage is malicious, a knowledge base contains contradictory entries, a citation is subtly wrong, or a tool returns attacker-controlled text. Production evaluation needs those adversarial cases.
OpenAI’s 2026 agent-security work makes the same architectural point: even if some injections succeed, the system should be designed so their impact is constrained. That is a more realistic objective than promising perfect prevention.
| Control | What it protects | What it cannot guarantee |
| Least privilege | Limits blast radius | Cannot stop a false answer inside allowed scope |
| Source provenance | Shows where evidence came from | Does not prove the source is truthful |
| Output validation | Stops malformed or unsafe structured output | Cannot determine every factual error |
| Human approval | Adds a decision gate for high-impact actions | Can fail if the approval UI hides context |
| Adversarial testing | Finds exploitable failure paths | Cannot prove future attacks will fail |
| Independent verification | Checks important claims against evidence | Adds time and operational cost |
The Security Trap: Letting One Model Police Another
It is tempting to solve prompt injection by adding a second language model that decides whether the first model has been manipulated. This can help, but it is not a complete security boundary.
An AI judge can itself be exposed to the same ambiguity between instructions and data. Lakera’s January 2026 analysis argues that LLM-based prompt-injection defences can create a recursive weakness when the security control shares the same failure modes as the system it protects.
The safer pattern is layered enforcement. Use deterministic policy checks where possible. Restrict permissions at the infrastructure level. Validate schemas in code. Use model-based classifiers as one signal rather than the sole authority. Keep sensitive credentials out of prompts and system messages. Require explicit approval for actions that create irreversible consequences.
OWASP’s guidance is aligned with this principle: model behaviour should be constrained, but the surrounding application should also enforce least privilege, input/output validation, segregation of untrusted content and human approval.
In other words, do not build a castle whose only door lock is another chatbot. AI Hallucination Rate Comparison 2026.
What “Safe Enough” Looks Like in Practice
There is no universal safe configuration because risk depends on what the AI is allowed to access and what happens when it is wrong. A customer-support assistant that drafts replies has a different acceptable failure rate from an agent that changes bank details or deploys production code.
For a low-impact research workflow, a sensible baseline is source visibility, citations, user review and no autonomous external actions. For an internal knowledge assistant, add permission-aware retrieval, document provenance, tenant isolation and audit logs. For an agent with write access, add narrow tool scopes, structured arguments, approval gates, monitoring and rollback.
Google Cloud’s 2026 Mandiant report is instructive here because its case studies show that prompt injection becomes materially more serious when the AI has access to internal repositories, external domains, credentials or operational systems. The model does not need unlimited intelligence to create damage; it needs an exploitable path plus sufficient authority.
The objective should therefore be risk containment, not a claim that the model can never be fooled. A system can tolerate occasional model error if the error remains a draft. It becomes much harder to tolerate when the same error can trigger a payment, disclose confidential data or change production infrastructure.
The final design question is brutally simple: if the model is wrong tomorrow, what is the maximum harm it can cause before a human or deterministic control stops it?
Our Editorial Verification Process
This article was researched on 27 September 2026. The editorial process began with attempts to fetch perplexityaimagazine.com/sitemap.xml, sitemap_index.xml and post-sitemap.xml. Those XML endpoints were not parseable through the available browsing path, so no sitemap entries were fabricated. Internal links were instead selected from live, indexed Perplexity AI Magazine pages with direct semantic relevance to hallucination, retrieval, agents, accuracy and AI-tool security. Each selected URL is used once in a body section.
For the search-result review, we examined ten prominent close-intent results for questions around whether AI can be hacked, manipulated through prompt injection, or made to return false information. The recurring structures were vulnerability lists, prompt-injection explainers, generic AI-hacking guides and hallucination explainers. The article was deliberately reorganised around the information trust chain rather than reproducing those sequences.
Technical claims were cross-checked against OWASP’s 2025 LLM risk framework and prompt-injection prevention guidance, OpenAI’s 2026 prompt-injection and agent-security publications, Google’s 2026 threat-intelligence research, Microsoft’s 2026 prompt-abuse research, Google Cloud Mandiant’s September 2026 AI Risk and Resilience Report, and peer-reviewed or research literature on prompt injection, misinformation and attacks by content.
Pricing was checked against current public vendor pages for ChatGPT, Claude, Gemini and Perplexity. Prices are presented only as a dated snapshot and are not treated as evidence of security performance. Named quotations were checked against the cited 2026 publications. Where a source did not establish a universal rate or guarantee, the article states the limitation rather than converting a study-specific observation into a general claim.
This article was researched and drafted with AI assistance and reviewed by the Awais Khalid editorial desk at Perplexity AI Magazine. All data, citations, pricing figures, and named quotes have been independently verified against primary sources before publication.
Conclusion
AI tools can be manipulated to produce false information, but the phrase “hacked AI” hides several different failure modes. A model can hallucinate without an attacker. An attacker can inject instructions into a prompt or external document. A knowledge base can be poisoned with misleading content. An application can trust an unsafe model output. Or a conventional software vulnerability can expose the infrastructure around the model.
The most important shift in 2026 is that AI systems increasingly operate as information brokers and agents rather than isolated chatbots. They read webpages, documents and messages, retrieve data, call tools and sometimes act on a user’s behalf. Every additional capability creates another trust boundary.
That does not make AI unusable. It changes what responsible use looks like. Users should verify consequential claims and review unexpected actions. Developers should treat external content, model output and tool results as untrusted until validated. Security teams should measure the complete workflow rather than a model in isolation.
The unresolved question is not whether an AI model can ever be fooled. Current evidence says manipulation remains a live security problem. The more useful question is whether the surrounding system is designed so that being fooled produces a harmless wrong sentence rather than a data breach, fraudulent recommendation or irreversible action.
FAQs
Can AI tools be hacked to give false information?
Yes. Attackers can manipulate some AI applications into producing false or misleading information, especially through prompt injection, poisoned retrieved content or unsafe integrations. However, a wrong AI answer alone does not prove hacking: hallucination and ordinary retrieval errors can occur without an attacker.
Is prompt injection the same as hacking?
Not exactly. Prompt injection is an attack technique that manipulates an AI system through crafted or attacker-controlled content. It can occur without compromising the underlying model infrastructure. Whether it becomes a broader security breach depends on what data, tools and permissions the affected application exposes.
Can a webpage make an AI assistant give a wrong answer?
Yes, if the assistant retrieves and processes the page as untrusted content without adequate separation and validation. Hidden or misleading instructions can influence an AI agent’s behaviour. The risk is higher when the agent can also call tools or act on the user’s behalf.
Can RAG prevent AI hallucinations?
RAG can reduce some unsupported answers by supplying relevant evidence, but it does not eliminate hallucinations or security risks. Retrieval can return stale, incorrect or attacker-controlled material, so provenance, permission filtering, source quality and claim verification remain necessary.
How can I tell if an AI answer was manipulated?
You usually cannot tell from the prose alone. Check the cited evidence, look for unexplained recommendations or instructions, compare important claims with independent sources and review any request for unusual permissions or actions. Treat high-impact answers as claims requiring verification rather than as authoritative facts.
Does paying for ChatGPT, Claude, Gemini or Perplexity make AI safer?
A paid plan can provide more models, usage or capabilities, but price does not establish immunity from prompt injection or misinformation. Security depends on the product’s architecture, permissions, retrieval controls, monitoring and the user’s workflow.
What is the biggest security risk when an AI can take actions?
The blast radius grows because a manipulated answer can become a tool call or external action. Excessive permissions, weak approval gates, unsafe tool arguments and untrusted retrieved content can turn a factual error into a security or operational incident.
What is the best defence against AI misinformation attacks?
Use layered controls: least-privilege access, trustworthy source selection, provenance, output validation, independent verification, adversarial testing, logging, human approval for high-impact actions and clear rollback paths. No single prompt or model-level filter is a complete defence.
References
- Open Worldwide Application Security Project. (2025). LLM01:2025 Prompt Injection.
- Open Worldwide Application Security Project. (2025). LLM09:2025 Misinformation.
- OpenAI. (2026). Understanding prompt injections.
- Google Threat Intelligence Group. (2026). AI threats in the wild: The current state of prompt injections on the web.
- Microsoft Defender Experts. (2026). Detecting and analyzing prompt abuse in AI tools.
- Google Cloud / Mandiant. (2026). AI Risk and Resilience Report 2026.
- Schlichtkrull, M. (2025). Attacks by Content: Automated Fact-checking is an AI Security Issue.
- Geng, T., Xu, Z., Qu, Y., & Wong, W. E. (2026). Prompt Injection Attacks on Large Language Models: A Survey of Attack Methods, Root Causes, and Defense Strategies.
- Perplexity. (2026). Which Perplexity subscription plan is right for you?