You can know whether an AI explanation of a concept is correct only by testing the explanation against an independent truth source and against the concept’s own logic—not by judging how clear, confident or detailed the AI sounds. That matters because a polished explanation can be wrong in exactly the way that is hardest to notice: it can preserve the vocabulary of a subject while quietly changing a definition, skipping a condition, reversing cause and effect, or turning a useful simplification into a false rule.
The practical goal is therefore not to “trust AI” or “distrust AI.” It is to separate comprehension from verification. An AI assistant may be excellent at rephrasing a difficult idea, generating analogies and answering follow-up questions, yet the explanation still needs an external standard. NIST’s Generative AI Profile calls confidently false output “confabulation” and explicitly warns that models can produce false logic or citations that appear to justify an answer. Stanford’s 2026 AI Index likewise shows a jagged reliability frontier: frontier systems can perform strongly on difficult benchmarks while still failing badly on particular tasks and hallucination tests.
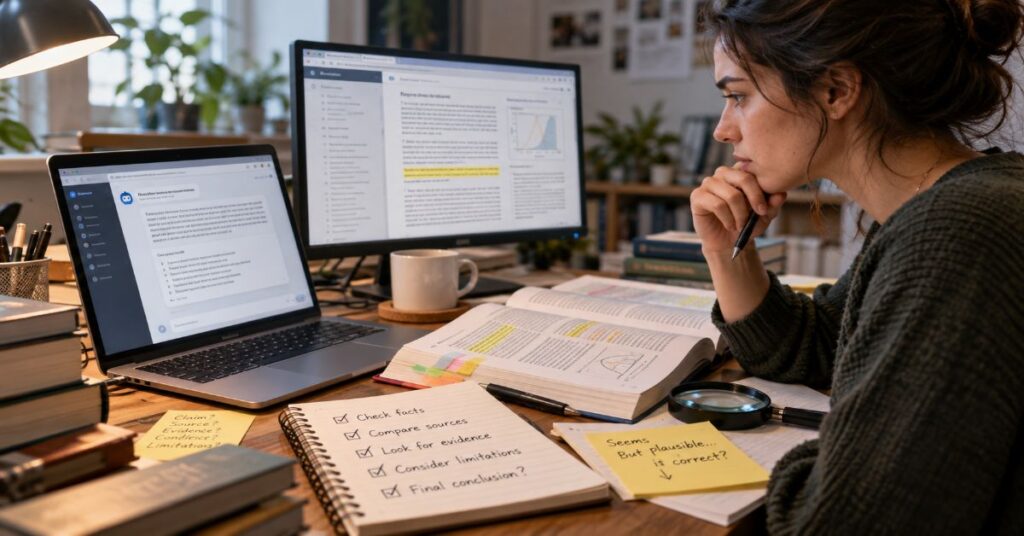
For a student, researcher or professional, the fastest reliable method is a layered check. First, define what the concept should mean using a textbook, standard, original paper or authoritative documentation. Second, break the AI explanation into claims and causal steps. Third, test whether each step follows, whether the same explanation handles a counterexample, and whether the AI changes its story when you rephrase the question. Finally, close the chat and explain the concept yourself. If you can reproduce the idea, its conditions and one example without leaning on the model’s wording, you have evidence of understanding rather than familiarity.
This guide develops that process into a repeatable verification system.
What Does “Correct” Mean for an AI Explanation?
A concept explanation can fail even when every sentence sounds plausible, because “correct” has more than one layer. The strongest explanations satisfy at least five tests: definition, mechanism, scope, example and transfer.
Definition asks whether the explanation states what the concept actually is. Mechanism asks whether it correctly explains how or why the concept works. Scope asks whether it states the conditions under which the explanation holds and the cases where it does not. Example asks whether the illustration genuinely instantiates the concept rather than merely sounding related. Transfer asks whether the explanation helps you solve a new case without copying the original wording.
This distinction is more demanding than ordinary fact-checking. A claim such as “water boils at 100°C” can be checked against a reference, but an explanation of why boiling point changes with pressure has a chain: vapour pressure, external pressure and the condition at which bubbles can persist. A model can get the headline right while getting the mechanism subtly wrong. The same is true in economics, law, statistics, machine learning and history. A definition may be accurate while the causal story is oversimplified; an example may be memorable while violating a boundary condition.
A useful rule is to treat clarity and correctness as separate variables. Clear language helps you inspect an explanation, but it does not validate it. Our guide to AI hallucinations and the 2026 trust test shows why: hallucination is not limited to invented names or fake citations; it can include unsupported reasoning that produces a believable account.
The Five-Layer Correctness Test
Start by writing the concept in one sentence from an authoritative source. Then ask five questions. Is the AI using the same core definition? Does every causal step follow from the last? Are important assumptions visible? Does the example fit the rule? Can the rule survive a new example?
If any answer is “no” or “unclear”, the explanation is not ready to rely on. That does not mean the whole response is useless. It means you have found the precise layer that needs correction.
| Layer | Question to ask | Typical hidden error |
| Definition | Is this the same concept the authoritative source defines? | Near-synonyms treated as identical |
| Mechanism | Does each causal or logical step follow? | Correct conclusion with invented reasoning |
| Scope | When does the rule hold or fail? | Usually becomes always |
| Example | Does the example truly instantiate the concept? | Memorable analogy replaces mechanism |
| Transfer | Can I use it on a fresh case? | Recognition mistaken for understanding |
The Seven Checks That Catch Most Concept Errors
A high-quality verification process should catch errors quickly, not turn every study session into a literature review. The seven checks below are ordered by information value: each one is designed to expose a different class of failure.
1. Compare the Definition With a Primary Source
Open the most authoritative source available for the concept. For a school topic, that may be the assigned textbook, teacher notes or exam board specification. For a scientific concept, prefer a standard reference, review article or original paper. For software, use official documentation. For law, use legislation, judgments or regulator guidance.
Do not ask whether the source “looks similar.” Compare nouns, conditions and exclusions. AI explanations often become wrong at the edges: “usually” becomes “always”, correlation becomes causation, a rule for one jurisdiction becomes universal, or a model-specific behaviour becomes a general property of AI.
2. Break the Explanation Into Claims
One paragraph may contain six claims. Number them. Definitions, dates, equations, causal statements, comparisons and exceptions should each become separate lines. This prevents one correct sentence from giving credibility to a neighbouring false one.
Our guide on whether AI-provided links can be trusted makes the same point from the citation side: a working source is not proof that every clause of a generated sentence is supported. Claim-level checking is the unit that matters.
3. Rebuild the Reasoning Without the AI
For maths, recompute the steps. For science, draw the process. For history, reconstruct the timeline. For programming, run the code or a test case. For a conceptual argument, write premises and conclusion.
This is the most underused check because it creates friction. It is also one of the most valuable. If the explanation only feels obvious while you are looking at the AI’s prose, you may be experiencing familiarity rather than understanding.
4. Ask for a Boundary Case
Prompt the model with a case where the concept almost applies but not quite. If the explanation is robust, it should distinguish the boundary. Ask, “When would this explanation fail?” or “Give me a counterexample that looks similar but is not an instance of the concept.”
Weak explanations often collapse here. They can produce a central example but cannot specify the edge of the category.
5. Ask the Same Question a Different Way
Change the wording, audience or starting assumption. For example: “Explain this to a beginner,” then “Explain it using the formal definition,” then “What would an expert object to in your first explanation?” Large differences are not automatically evidence of error, but contradictions are a red flag.
why different AI tools give different answers is partly explained by model training, retrieval, system instructions and prompt sensitivity. Agreement between chatbots is therefore not independent corroboration.
6. Try to Falsify the Explanation
Do not ask the AI to confirm itself. Ask what evidence would prove its explanation wrong. Search for the strongest opposing case. In science, this may mean checking whether the mechanism predicts an observable outcome. In social science, it may mean asking whether the explanation ignores a confounder. In philosophy, it may mean identifying a counterexample.
7. Perform the Closed-Chat Test
Close the AI window. Explain the concept in your own words, including one condition and one example. Then answer a new question. If you cannot do that, you have not yet demonstrated transferable understanding.
A 2026 qualitative study of doctoral learners captured this problem sharply: participants described AI explanations that felt clear but blurred the boundaries between related constructs. One participant’s workaround was simple—close the page and try to explain the theory independently. That is a useful metacognitive test because it measures what remains after the fluent wording disappears.
Use the Right Source for the Kind of Claim
The best source depends on what kind of concept you are checking. “Use reliable sources” is too vague to be operational. Authority is contextual.
For a medical mechanism, a recent clinical guideline or systematic review may be appropriate. For a mathematical definition, a textbook or formal reference is more useful than a news article. For a product feature, the vendor’s documentation is primary evidence. For a historical interpretation, primary documents establish events while scholarly work helps interpret them.
The crucial distinction is between a source that owns the fact and a source that comments on it. An official vendor page can establish its current feature list, but it cannot independently prove that its product is the most accurate. A company press release can establish what the company announced, but not whether the claim is objectively true.
Match Evidence to the Claim
A good verification habit is to ask, “Who would be accountable for this fact if it were wrong?” That often points to the correct source class. A regulator owns a regulation. A standards body owns a standard. The original research team owns the study’s methods and reported results. An exam board owns its syllabus. The software vendor owns its documented API behaviour.
This source hierarchy also reduces a common AI-search trap: five pages can appear to confirm a claim while all five repeat the same original press release. Independent-looking links are not necessarily independent evidence.
For current information, check two dates: the publication date of the page and the date to which the fact applies. A current article can quote an old policy. A live pricing page can describe a legacy plan. A paper can be new while analysing older data. Currency is part of correctness.
| Claim type | Best first source | What to verify |
| Course concept | Assigned text / syllabus | Definition, notation, expected scope |
| Scientific mechanism | Review / original research | Mechanism, assumptions, evidence |
| Software behaviour | Official documentation | Version, platform, limits |
| Law or regulation | Government / regulator / judgment | Jurisdiction, date, exceptions |
| Statistic | Original dataset / study | Denominator, period, methodology |
| Historical claim | Primary record + scholarship | Event vs interpretation |
Verification Changes by Subject
The verification method should change with the kind of concept. A single generic checklist wastes time and misses domain-specific errors. Our guide to which subjects benefit most from AI for studying reaches the same conclusion from the learning side: the value and risk of AI depend on the job being done.
Maths and Statistics
Recalculate. Definitions and algebraic transformations can often be verified deterministically. Ask the AI to state assumptions, then test a small numerical case. Watch for division by zero, sign errors, hidden independence assumptions and confusion between population and sample quantities.
Physics, Chemistry and Biology
Check units, conservation constraints, causal direction and limiting cases. A good explanation should still make sense at an extreme value. If an explanation says increasing pressure raises boiling point, ask what happens in a vacuum and why. If a biological pathway is described, verify the direction and location of each step against a trusted reference.
Computer Science
Run the code, inspect official documentation and construct adversarial tests. AI can explain an algorithm correctly but give code with a version-specific API mistake. Conversely, code may pass one example while violating the claimed complexity or security property. Separate conceptual correctness from implementation correctness.
History and Humanities
Distinguish event, interpretation and argument. Dates and quotations require evidence; interpretations require context and competing scholarship. An AI explanation may flatten contested debates into a single narrative. Ask which parts are widely agreed, which are disputed, and what primary evidence supports each interpretation.
Law, Policy and Social Science
Check jurisdiction, effective date, definitions and exceptions. In economics and social science, look for hidden assumptions, causal overreach and omitted variables. Models often turn “associated with” into “causes”. Ask whether the explanation is descriptive, causal or normative, and which evidence would distinguish those categories.
Red Flags That Should Trigger a Deeper Check
Some warning signs deserve immediate scrutiny because they predict a higher chance of error or overreach.
The first is precision without provenance: an exact percentage, date, quotation or technical limit appears with no traceable source. The second is universal language—“always”, “never”, “all models”, “in every case”—for a concept that normally has conditions. The third is a missing denominator: the AI gives a statistic without explaining the sample, baseline or time period.
The fourth red flag is analogy substitution. Analogies are useful for intuition, but the analogy is not the mechanism. “Electric current is like water flowing through pipes” can support a beginner’s intuition while obscuring important differences. A correct explanation should be able to state where the analogy breaks.
The fifth is self-citation. Asking the model “Are you sure?” and receiving a more confident version is not verification. The same system is being asked to grade its own output. The 2026 Nature paper by Adam Tauman Kalai and colleagues argues that common accuracy evaluation incentives can reward guessing rather than abstention, helping explain why confident completion can persist when uncertainty would be more appropriate.
The sixth is story repair. When challenged, the model invents a new rationale instead of acknowledging the original mistake. NIST explicitly warns that generated logic can itself be confabulated.
The seventh is source laundering. A citation exists, but it does not support the exact claim. This is especially common when an answer synthesises multiple pages and attaches one citation to a sentence with several propositions.
Confidence Is Not a Reliability Metric
OpenAI’s own help guidance tells users that ChatGPT can produce incorrect definitions, facts, studies and citations while sounding confident. The lesson is not unique to ChatGPT: tone cannot serve as a proxy for truth.
Stanford’s 2026 AI Index reports wide variation in hallucination behaviour across models and tasks, reinforcing a jagged reliability frontier. A model that is excellent on one benchmark may be poor on another. why AI gives confident wrong answers is therefore a more useful question than simply asking which model is “smartest”.
| Red flag | Why it matters | Best response |
| Exact number, no source | Precision can be fabricated | Find original data |
| Always / never language | Conditions may be missing | Ask for exceptions |
| Analogy presented as mechanism | Intuition can hide false structure | State where analogy breaks |
| AI cites itself | Not independent verification | Use external evidence |
| Source exists but claim differs | Citation laundering | Read supporting passage |
| Answer changes after rephrasing | Possible instability | Identify contradiction and verify |
A 90-Second Check and a Full Evidence Audit
A practical workflow should be fast enough to use every day. The most efficient approach is a two-pass audit.
Pass One: The 90-Second Sanity Check
First, identify the central definition and one mechanism. Search an authoritative source and compare the wording. Then inspect any exact number, named study, quotation or rule. Finally, ask the AI for one boundary case and one uncertainty.
If the response passes, you have reasonable confidence for low-stakes learning. If it fails, move to the second pass.
Pass Two: The Evidence Audit
Break the explanation into claims. Mark each as verified, inference, simplification or unsupported. Reproduce calculations, inspect the original source passages and test a counterexample. For important work, ask a domain expert or use a second independent source.
This risk-based approach is better than checking everything equally. A wrong analogy in a casual overview costs little. A wrong dosage, legal deadline, safety rule or engineering assumption can create harm.
The same principle should determine how you use AI tools. Our comparison of AI systems for answering questions shows that browsing, citations, file grounding and workflow controls can make verification easier, but none eliminates the need to inspect evidence.
A Simple Decision Rule
If the cost of being wrong is low and the claim is easy to reverse, a quick check is usually enough. If the claim is consequential, time-sensitive, technical or hard to reverse, verify it against primary evidence before acting.
This gives users a better standard than blanket trust or blanket scepticism. It also scales: the same risk ladder works for a student checking a definition, an analyst checking a market figure and an engineer checking an implementation claim.
| Situation | Verification level | Minimum action |
| Casual curiosity | Light | Definition + one credible source |
| Homework / study | Moderate | Course source + closed-chat transfer test |
| Published content | High | Claim-level sources + citation support check |
| Money / legal / health / safety | Very high | Primary evidence + qualified human review |
| Irreversible technical action | Very high | Documentation + test environment + peer review |
Worked Examples: How the Test Exposes Subtle Errors
The verification framework becomes easier to use when you see what a “nearly right” explanation looks like. The following examples are deliberately simple; the point is the method, not the subject matter.
Example 1: Correlation and Causation
Suppose an AI says: “Ice-cream sales cause sunburn because both rise during summer.” The vocabulary is plausible but the causal mechanism is wrong. The definition check separates correlation from causation. The falsification check asks whether a third variable—temperature and sunny weather—could increase both. The boundary check asks whether ice-cream sales would still predict sunburn indoors or in cold weather.
A correct explanation should identify the confounder and explain why correlation alone does not establish the direction of causation.
Example 2: Natural Selection
An AI might say: “Animals evolve traits because they need them to survive.” That sentence is memorable and wrong enough to mislead. The mechanism check reveals the problem: individuals do not intentionally acquire heritable traits because of need. Variation already exists or arises; differential survival and reproduction change trait frequencies across generations.
The transfer test then asks you to explain antibiotic resistance or camouflage without using the phrase “because they needed it”. If the explanation survives the new example, your mental model is improving.
Example 3: Software Complexity
An AI might correctly define binary search but claim its worst-case time complexity is O(n). Here the easiest verification is executable reasoning: each comparison halves the remaining search space, so the number of steps grows with log2(n). A small table for n = 8, 16 and 32 exposes the pattern immediately.
This is why domain-specific tests matter. A citation hunt is slower and less informative than reconstructing the algorithm.
Example 4: A Historical Explanation
Suppose a model says a war began “because of” a single assassination. The event may be factual, but the causal explanation is too narrow. Source checking confirms the triggering event; mechanism and scope checks then ask about alliances, mobilisation plans, imperial competition, nationalism and prior crises. A good explanation distinguishes trigger from background causes rather than converting chronology into a monocausal story.
Prompts That Make AI Explanations Easier to Audit
Prompts can make an AI explanation easier to audit, but prompts cannot turn the model into an independent source of truth. The useful goal is to expose uncertainty, assumptions and evidence.
A strong verification prompt asks the model to separate what is stated by a source from what it is inferring. For example: “Explain the concept, then list the assumptions, boundary conditions and the three claims most likely to be wrong. Do not invent citations. If you are uncertain, say so.”
Another useful pattern is adversarial tutoring: “Give me the best explanation, then give me a counterexample that would break an oversimplified version.” This forces the model to reveal the edges of its rule.
For study, ask the model to delay the final answer. Have it pose a question, request your reasoning and only then provide feedback. That turns AI from an answer machine into a practice environment. Our analysis of whether AI can explain textbook chapters better than teachers found that explanation quality is only one part of learning; motivation, diagnosis, feedback and transfer matter too.
Do Not Ask the Model to Certify Itself
Prompts such as “double-check your answer” can improve output, but they are not independent verification. The model may correct itself, repeat itself or confidently produce a different error. A second model can be useful for generating alternative explanations, but model agreement still does not replace an authoritative source.
The strongest prompt is therefore one that helps you inspect the answer, not one that asks the AI to declare the answer trustworthy.
The Bigger Risk: Mistaking Fluency for Understanding
The most dangerous failure is not an obviously wrong answer. It is an explanation that feels so smooth that you stop checking whether you could reconstruct it yourself.
Psychologists have long studied the “illusion of explanatory depth”: people often believe they understand familiar systems until asked to explain how they work. AI can intensify that effect because it supplies a coherent explanation instantly, removing the struggle that normally reveals gaps.
A 2026 Frontiers study of doctoral learners provides a useful modern example. Participants reported that AI could explain constructs clearly while sometimes mixing neighbouring concepts or blurring theoretical boundaries. Another participant described the corrective habit of closing the AI page and explaining the theory independently. That practice converts passive recognition into active retrieval.
This is where education-focused AI guidance becomes more nuanced. Sal Khan, founder of Khan Academy, said in 2026 that early Khanmigo use was “a non-event” for many students because they simply did not engage with it much. In a later interview, he argued that AI works best when woven into teacher-led systems rather than treated as a stand-alone replacement. The lesson for concept verification is similar: access to an explanation is not the same as learning the concept.
The Transfer Test
After reading an AI explanation, do three things without the AI. Define the concept in your own words. Produce a new example. Then explain one case where the concept does not apply.
If you can do all three accurately, you have evidence of a mental model. If you can only repeat the chatbot’s analogy, you have evidence of exposure.
This is also why “AI explained it better than my textbook” can be true while “I now understand it correctly” remains unproven. Ease of reading and durable understanding are different outcomes.
What 2026 Researchers and Educators Say About Verification
The strongest 2026 commentary points in the same direction: the value of AI depends less on whether it can produce an explanation and more on whether the surrounding workflow forces users to think, verify and notice uncertainty. That is a useful corrective to the idea that a more articulate model automatically creates a more trustworthy tutor.
Princeton cognitive scientist Tania Lombrozo, whose 2026 ACL keynote focused on explanation and understanding, has argued that explaining is itself part of how people discover gaps and generalise knowledge. In a July 2026 talk about learning in an age of information overload, she described AI-generated responses and chatbot explanations as “incredible tools” but warned that they should not replace the internal work of explaining and thinking. For verification, that means the user should not merely consume the model’s account; the user should actively reconstruct it.
Wharton professor Ethan Mollick made a complementary point in April 2026: “Hallucinations remain in LLMs,” but organisations already know how to reduce errors from uncertain sources through review structures. The implication is practical. Reliability is not a property you outsource to the model; it is an outcome produced by checks, source standards, escalation rules and human judgement.
Khan Academy founder Sal Khan offered a more educational warning after three years of AI tutoring experiments. He said Khanmigo was “a non-event” for many students because they did not engage with it much. His later reflections emphasised integration with teachers and learning systems rather than expecting a chatbot to create motivation on its own. A correct explanation that the learner never interrogates has limited educational value.
Phil Misecko, an assistant superintendent speaking with Khan Academy in March 2026, put the human-versus-tool trade-off plainly: “If I had to pick between amazing teacher, amazing technology, I’ll pick amazing teacher every time.” That does not reject AI. It identifies where responsibility sits when context, motivation, diagnosis or consequences exceed what an automated explanation can establish.
Together, these perspectives support a verification-first model. Use AI for speed, rephrasing, examples and challenge questions. Use authoritative sources for truth claims. Use your own reconstruction for understanding. Use qualified humans when the cost of error is high or the concept depends on context that a chatbot cannot reliably observe.
The Expert Consensus Is About Process, Not Blind Trust
None of these perspectives implies that AI explanations are generally useless or generally correct. The shared lesson is narrower: the explanation should sit inside a process that can catch error.
That process can be very light for ordinary learning and very strict for high-stakes work. What should not change is the direction of accountability. The AI proposes; evidence and human judgement decide. This is also consistent with the research on verifiability in AI-advised decision making: explanations improve outcomes only when users can use them to check whether the underlying conclusion is actually right.
Our Editorial Verification Process
This article was built as an explainer and verification guide rather than a product ranking. We first reviewed the current search landscape for the exact keyword and close variants including “how to verify AI answers”, “how to fact-check AI responses” and “how to tell whether an AI answer is reliable”. The leading pages repeatedly used a generic claim-extraction and source-checking structure. We therefore used a different organising model: five layers of conceptual correctness, seven failure-oriented checks, domain-specific verification and a transfer test for genuine understanding.
For factual grounding, we cross-referenced NIST’s Generative AI Risk Management Framework profile, OpenAI’s public guidance on ChatGPT accuracy, Stanford HAI’s 2026 AI Index, the April 2026 Nature paper by Adam Tauman Kalai and colleagues on hallucination incentives, 2026 peer-reviewed research on hallucination detection, and recent education research on AI-mediated learning and metacognitive calibration. We also used current reporting and first-party material from Khan Academy for the education context.
The live Perplexity AI Magazine sitemap.xml, sitemap_index.xml and post-sitemap.xml endpoints were attempted through the available browsing layer but did not return parseable XML. In line with the editorial fallback rule, internal links were selected only from live indexed Perplexity AI Magazine pages with direct semantic relevance to hallucinations, source verification, AI answers, study use and explanation quality. No URL was fabricated to hit a quota.
The article does not claim a universal hallucination percentage for AI explanations, because rates vary by model, benchmark, prompt, retrieval access and scoring method. It also does not treat agreement between chatbots as independent evidence. Pricing matrices and API-cap tables were not included because the search intent is conceptual verification rather than purchase evaluation; adding them would create irrelevant topical drift. Where a named AI product appears, it is used only to illustrate documented reliability or learning behaviour, not to make a commercial recommendation. This keeps the evidence burden aligned with the actual question instead of padding the article with product data that would not help a reader judge an explanation.
This article was researched and drafted with AI assistance and reviewed by the Sami Ullah Khan editorial desk at Perplexity AI Magazine. All data, citations, pricing figures, and named quotes have been independently verified against primary sources before publication.
Conclusion
The safest way to judge an AI explanation is to treat it as a hypothesis about the concept, not as the final authority. A correct explanation should match an authoritative definition, preserve the causal or logical structure, state its assumptions, survive a counterexample and help you solve a new case without the model beside you.
That standard is stricter than “the answer had citations” and more useful than “the AI sounded confident”. Citations can be mismatched, confidence is stylistic, and a simple explanation can hide an important exception. The decisive evidence comes from independent sources and from your ability to reproduce the reasoning.
The practical workflow is therefore compact: check the definition, break the explanation into claims, rebuild the reasoning, test a boundary case, verify high-stakes details and then close the chat. For low-stakes learning, this can take a minute or two. For consequential decisions, the evidence burden should rise with the cost of being wrong.
AI explanations are most valuable when they accelerate the path to understanding without becoming a substitute for verification. The open question for 2026 is not whether models will become more fluent; they already are. It is whether users, educators and organisations build habits that make fluent mistakes visible before those mistakes become decisions.
FAQs
How do I know if an AI explanation of a concept is correct?
Check the explanation against an authoritative source, then test its logic, assumptions, examples and boundary cases. Rebuild the reasoning yourself and close the chat to explain the concept in your own words. If a high-stakes claim cannot be independently verified, do not treat the AI answer as established fact.
Can I trust an AI explanation if it includes citations?
Not automatically. A citation can exist while failing to support the exact sentence beside it, or it may be outdated or secondary. Open the source, find the relevant passage and verify that its scope, date and level of certainty match the AI’s wording.
Is asking ChatGPT or another AI to double-check itself enough?
No. Self-checking can catch some mistakes, but the same model is still evaluating its own output and may repeat or replace one error with another. Use an independent source for verification; a second AI can generate alternatives but is not independent evidence.
Why can an AI give a clear explanation that is still wrong?
Language models are optimised to generate plausible continuations, not to guarantee that every statement is true. They can preserve familiar terminology while altering a condition, causal step or exception, so clarity and factual correctness must be evaluated separately.
What is the fastest way to verify a low-stakes AI explanation?
Use a 90-second check: confirm the definition in one authoritative source, inspect any exact number or named citation, ask for a boundary case and then restate the concept without looking at the AI. Escalate to a deeper audit if anything conflicts.
Should students use AI to understand difficult concepts?
Yes, AI can be useful for rephrasing, analogies, examples and practice questions, but it should not become the sole authority. Students learn more safely when they compare explanations with course material and test whether they can solve a fresh problem without AI assistance.
Does agreement between several AI tools prove an explanation is correct?
No. Models can share training data, common web sources and similar errors. Agreement can raise a useful question, but independent corroboration requires evidence that does not originate from the same AI information chain.
When should I ask a human expert instead of relying on AI?
Escalate when the concept affects health, safety, law, finance, engineering, professional responsibility or a high-stakes academic decision, especially when authoritative sources conflict or the AI cannot state its assumptions and limits clearly.
References
- National Institute of Standards and Technology. (2024). Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1).
- OpenAI. (2026). Does ChatGPT tell the truth? OpenAI Help Center.
- Stanford Institute for Human-Centered Artificial Intelligence. (2026). The 2026 AI Index Report.
- Kalai, A. T., Nachum, O., Vempala, S. S., & Zhang, E. (2026). Evaluating large language models for accuracy incentivizes hallucinations. Nature, 653, 1047–1051.
- Naser, M. Z. (2026). Hallucinations in generative artificial intelligence and large language models: tests, datasets, detection and correction methods. Language Resources and Evaluation, 60, 64.
- Waqas, S. M., Umer, Z., Alim, A., et al. (2026). Hallucination detection, verification, and correction in generative AI: A comprehensive survey. Natural Language Processing Journal, 16, 100231.
- Khan, S. (2026). Khanmigo’s first chapter changed how I think about AI. Khan Academy.
- Frontiers in Psychology. (2026). Cognitive offloading and metacognitive calibration in generative AI-mediated doctoral learning.